Introduction
Smartphone owners expect their favorite online applications to load instantly every single day. Daily internet networks carry millions of user requests, so hidden bugs trigger messy outages. Site Reliability Engineering provides a clear operational framework that keeps cloud software platforms from crashing. This discipline merges creative software programming with round-the-clock IT system administration. Developers write smart code routines to eliminate boring, repetitive maintenance headaches forever. Motivated engineers discover these practical operational habits through SRESchool.com. The online education portal provides structured guidance for aspiring students and enterprise engineering teams.
What Is SRESchool.com?
Reliable tools perform their assigned duties without failing you at unexpected moments. Consider a sturdy kitchen clock hanging quietly on your kitchen wall. You glance up and read the exact time whenever you enter the room. People trust that clock because the internal gears never stop ticking. Modern web services must run with that same predictable, rock-solid consistency. SRE enables technical teams to operate safe, crash-free applications for global audiences. Engineers measure system speeds, observe live data flows, and replace tedious manual chores with code. Teams examine past service interruptions so their software architectures grow stronger every month.
Why Does SRESchool.com Matter?
Enterprises launch complex applications across interconnected server networks known as the cloud. These large environments link web routers, backend code, and customer payment records. A surprise server shutdown instantly locks thousands of eager shoppers out of their accounts. Service breakdowns trigger angry customer complaints, destroy brand reputation, and erase business profits. Because of these huge business risks, SRE shows engineers how to spot small bugs early. Specialists resolve tiny defects before ordinary mobile users experience annoying lag or error messages. High service uptime delights customers and protects vital revenue streams every single day.
What Does an SRESchool.com Team Do?
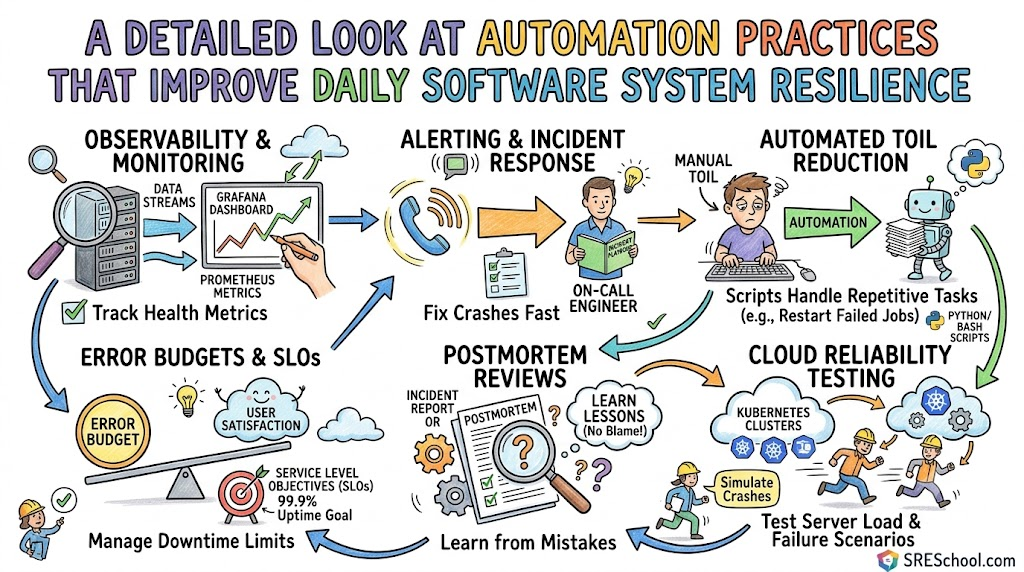
Engineers complete diverse, engaging tasks each day to guard production applications. They construct live telemetry monitors that measure database health and network traffic flows. Next, they configure smart notification alarms that ping engineers during sudden service dips. Squads rush forward to repair broken code whenever emergency outages hit production systems. Then engineers write clever automation scripts that handle dull administrative work automatically. Planners examine customer demand patterns so retail websites easily survive massive holiday rushes. Furthermore, engineers inspect upcoming feature updates to guarantee system safety before release. Finally, teams draft blameless postmortem summaries to capture helpful operational lessons from recent system crashes.
Key SRE Terms Made Easy
Reliability specialists apply distinct operational phrases to evaluate running digital applications. A Service Level Indicator, or SLI, shows your real-time performance score. A Service Level Objective, or SLO, names the target success standard. An Error Budget marks the small fraction of allowable system errors. Observability allows specialists to understand system health by evaluating logs, metrics, and network traces. Next, toil denotes tedious, manual administrative tasks that simple scripts could execute. On-call shifts require engineers to carry notification devices to resolve sudden midnight server crashes. Lastly, an incident is an unexpected system malfunction that demands immediate engineering attention.
| SRE Term | Simple Meaning | Example |
| SLI | A real health measurement | Checkout request speed |
| SLO | The agreed safety goal | 99.5% fast page views |
| Error Budget | Room for small mistakes | 0.5% permitted errors |
| Toil | Boring repeated work | Rebooting stuck machines |
| Observability | Looking inside running systems | Inspecting server traces |
| Incident | A sudden software breakdown | A broken user login form |
What Is SRE Training?
Ambitious candidates gain strong technical capabilities through structured SRE Training. Students study foundational computing topics, clear performance standards, and real-time metric tracking. They create diagnostic telemetry dashboards and manage simulated emergency outages inside safe practice labs. Next, trainees write custom automation tools to eliminate slow, exhausting manual operations. They also analyze cloud patterns that shield multi-region architectures against sudden hardware disasters. Realistic laboratory exercises teach students how to fix broken platforms without jeopardizing live customer data. Curious technologists can begin this structured professional path at SRESchool.com. Deep technical practice builds skilled, confident platform engineers who thrive under pressure.
What Is SRE Certification?
An SRE Certification demonstrates verifiable mastery over production reliability and infrastructure management. A Certified Site Reliability Engineer monitors key service metrics and directs fast incident restorations. These accredited professionals also lead blameless retrospective reviews after serious platform failures occur. Structured learning curricula give students a clear roadmap toward deep technical proficiency. However, a paper credential cannot replace real keyboard time on actual production systems. Candidates must configure real servers, run terminal commands, and create dependable automation routines. Lasting career advancement requires combining formal classroom theory with messy hands-on problem solving.
What Is a Site Reliability Engineering Course?
An effective Site Reliability Engineering Course leads learners down an orderly developmental track. First, candidates study fundamental computing concepts, networking protocols, and basic operating systems. Next, students deploy tracking probes, collect live telemetry data, and define realistic SLO targets. Then learners resolve practice service outages and automate boring operational chores with clean code. Afterward, students navigate distributed cloud environments and examine historical case studies of major industry crashes. This progressive curriculum turns eager beginners into capable, highly valued cloud operators. Both aspiring computer students and experienced system administrators gain valuable modern engineering skills.
SRE Tools Made Simple
Engineers operate sophisticated software programs to inspect and defend complex cloud platforms. Monitoring agents scan running machines continuously to inspect memory allocations and processor heat. Visual dashboards convert raw metric numbers into crisp graphical summaries that teams grasp instantly. Distributed tracing packages follow single user requests through complex webs of microservices. Alerting utilities trigger emergency alarms whenever critical transaction failures exceed safe baseline levels. Widely adopted industry tools include Prometheus, Grafana, and robust OpenTelemetry frameworks. These powerful software suites help vigilant engineers identify system defects and restore platform health rapidly.
| Learning Area | What Learners Can Practice |
| Monitoring | Gathering system numbers with Prometheus probes |
| Visual Boards | Designing custom telemetry panels inside Grafana |
| Tracing | Tracking microservice requests with OpenTelemetry |
| Alerting | Paging engineers when checkout latency spikes |
| Automation | Launching shell scripts to purge temporary disks |
Real-Life Scenarios / Experiences
- An online food delivery application buckled under dinner orders, so engineers added auto-scaling rules that launch fresh web servers automatically.
- A streaming video portal ran out of disk space every Friday, prompting engineers to schedule a cron job that archives old video previews.
- A banking application threw mysterious database errors during high traffic, leading the team to add circuit breakers that stop cascading crashes.
- Developers spent four hours every morning running repetitive server checks, so they built a lightweight script that completes the chore in seconds.
What Is SRE Consulting?
SRE Consulting connects growing digital businesses with seasoned reliability experts who deliver targeted advice. These experienced practitioners review existing software setups to expose hazardous single points of platform failure. They coach software developers toward realistic SLO targets and streamline awkward incident response steps. Consultants also demonstrate how to sweep away manual operational toil using automated pipelines. Next, they create clear business continuity strategies so organizations weather unexpected cloud datacenter outages smoothly. This targeted expert guidance transforms brittle, crash-prone systems into dependable web platforms that earn customer trust.
What Is SRE as a Service?
Fast-growing startups frequently lack the massive operating budget needed to hire full-time platform engineering departments. Instead of struggling alone, lean businesses choose SRE as a Service for steady operational coverage. Remote reliability professionals monitor system vital signs around the clock and act swiftly when problems emerge. These external engineers patch security flaws, optimize expensive cloud bills, and manage sudden production emergencies. They also run routine disaster recovery drills to verify that database backups restore cleanly. However, business owners must document their exact operational expectations before retaining an external engineering partner.
What Is Corporate SRE Training?
Mature tech companies choose Corporate SRE Training to align their software engineering teams around unified operational principles. This group instruction teaches programmers and operations personnel how to cooperate during high-stakes system failures. Everyone adopts a common technical language, measures matching error budgets, and executes calm incident triage steps. Team members assemble inside realistic staging sandboxes to troubleshoot sabotaged server clusters together. These practical drills strengthen inter-team empathy and elevate technical debugging capabilities. Coordinated reliability education empowers modern companies to launch new digital features without inducing catastrophic system blackouts.
Common Mistakes to Avoid When Choosing Delhi Events
- Demanding impossible 100% platform uptime that leaves zero room for software innovation.
- Ignoring manual toil until hardworking engineers burn out and seek different employers.
- Flooding screens with noisy, low-priority alerts that teach staff to ignore warnings.
- Punishing good engineers for unintended human errors during messy production outages.
- Bypassing security reviews and automated testing just to hit artificial product deadlines.
- Storing system backups on unreachable drives without running monthly recovery drills.
- Designing tangled, overcrowded telemetry dashboards that baffle engineers during real crises.
- Renaming the old operations team without introducing modern software automation practices.
How SRESchool.com Can Help
SRESchool.com delivers deep educational pathways for ambitious learners and working engineering professionals. Students can dive into comprehensive SRE Training modules or explore a clear, self-guided SRE Tutorial. The platform features an extensive Site Reliability Engineering Course complete with realistic hands-on laboratory environments. Learners gain the exact skills needed to graduate as a Certified Site Reliability Engineer. The academy also offers deep, practical explorations of popular modern SRE Tools. Furthermore, businesses can engage expert SRE Consulting to audit system architecture and improve incident triage. Growing enterprises also utilize SRE as a Service alongside targeted Corporate SRE Training programs. This complete learning hub equips individuals and companies to build resilient digital systems.
Frequently Asked Questions
1. What is Site Reliability Engineering in simple terms?
Engineers use software programming methods to solve traditional systems operations headaches. Rather than fixing recurring server breakdowns by hand, developers construct automation routines that repair infrastructure automatically. This practical methodology keeps popular mobile apps, cloud tools, and gaming platforms running smoothly without expensive crashes.
2. Must I learn programming before exploring SRE?
Basic programming experience certainly makes your initial learning journey much smoother. You do not need twenty years of software architecture experience to start. Learning introductory Python, Go, or Linux command-line scripting helps you automate tedious operational tasks quickly.
3. How does SRE differ from general DevOps practices?
DevOps describes a cultural movement that urges development and operations personnel to collaborate. SRE delivers concrete technical metrics, formulas, and actionable operational rules to achieve that cultural vision. SRE provides the exact numerical targets and tools that bring abstract DevOps philosophies to life.
4. Why do engineering teams care about Error Budgets?
Error budgets balance the desire for rapid feature rollouts with user demands for stable software. When platforms run reliably, developers spend their surplus budget releasing fun updates. If bugs exceed that safety margin, teams pause feature launches and repair broken code immediately.
5. Can complete tech beginners take an SRE course?
Curious beginners with basic operating system and computer networking skills can start studying immediately. Quality courses explain foundational concepts clearly before introducing complex infrastructure troubleshooting scenarios. Step-by-step guidance helps new students master monitoring, automation, and incident mitigation without drowning in technical jargon.
6. How does software automation protect human teams?
Automation transfers dull, repetitive administrative chores away from tired humans to fast computer scripts. Engineers make typographical errors when executing manual terminal commands during midnight emergencies. Reliable automated programs finish these tasks accurately every single time, allowing humans to focus on creative engineering challenges.
7. Which duties fall on an on-call engineer during a shift?
On-call specialists monitor system alerts and resolve urgent platform breakdowns during assigned shifts. If a critical database stops responding at midnight, the paging system calls the on-call engineer. The engineer opens the logs, fixes the broken component, and documents the event for the team.
8. How does monitoring differ from true system observability?
Monitoring tells operators that an individual application service has stopped working. Observability allows engineers to deduce why that failure occurred by examining deep diagnostic telemetry data. Monitoring notifies you about an active house fire, whereas observability reveals the faulty electrical outlet that started it.
9. Which benefits come from corporate reliability instruction?
Team training unites software developers, system administrators, and product managers under shared operational standards. Everyone learns how to handle software outages collaboratively without blaming coworkers for unexpected bugs. This shared operational discipline prevents humiliating service downtime and keeps paying consumers loyal.
10. When should a business consider SRE as a Service?
Budget-conscious startups hire external reliability teams when hiring full-time internal platform engineers costs too much money. External specialists provide 24/7 monitoring coverage, patch security gaps, and manage platform crises efficiently. This flexible model gives growing companies immediate access to senior cloud expertise on predictable monthly terms.
11. What value does a postmortem deliver to an engineering organization?
A postmortem examines a recent software disruption to uncover root causes and architectural weaknesses honestly. Teams skip personal blame and focus entirely on fixing fragile code and broken deployment processes. These candid written summaries teach organizations how to avoid repeating the exact same technical blunders later.
12. How do reliability consultants help growing tech organizations?
External advisors inspect existing cloud platforms to expose dangerous operational vulnerabilities before disasters strike. They help executive teams define realistic SLO goals that mirror true user satisfaction levels. These veteran mentors also establish efficient emergency response procedures that keep engineering squads calm during outages.
Conclusion
Modern digital systems require strong reliability engineering principles to survive unpredictable internet traffic surges. The discipline unites practical computer coding with daily operational maintenance to deliver dependable online software. Engineering squads establish clear SLO goals, track live telemetry with SLIs, and automate away painful manual toil. Determined professionals can master these essential technical disciplines through interactive coursework and realistic lab practice. In addition, forward-thinking enterprises can leverage professional consulting services to harden their distributed cloud infrastructure. Helpful educational hubs like SRESchool.com guide learners through training, industry certifications, and enterprise advisory services. Investing in modern reliability engineering guarantees fast, stable digital services that users can trust forever.
